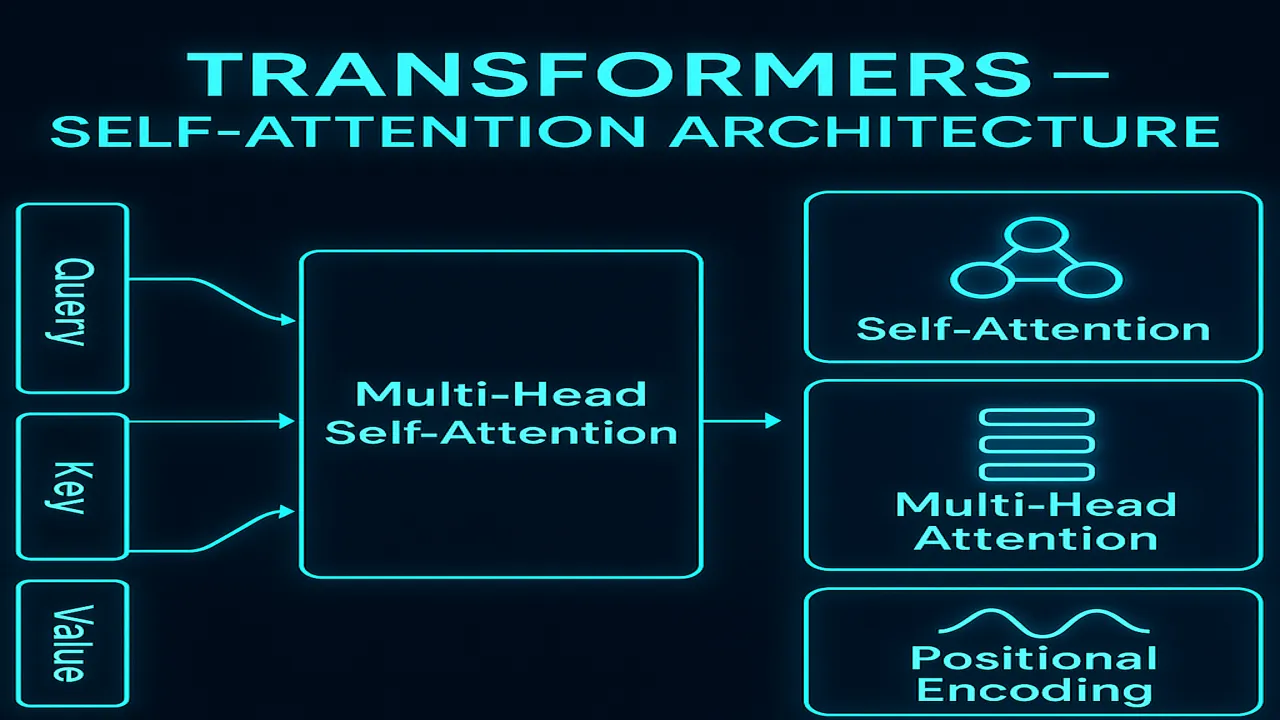
Lecture 15 – Transformers in Deep Learning: Architecture, Self-Attention, Multi-Head Attention & Positional Encoding
Introduction Transformers are the most powerful and game-changing architecture in modern deep learning. From BERT and GPT-4 to Stable Diffusion and Gemini…
Read guide